
I periodically promise my wife I will stop writing about RCTs and just write about my own research. But eventually I break down. In this case there are two reasons.
One, I started a paper as a homage to Edward Leamer, who was in some sense a father of the “credibility revolution” but that paper morphed into a published paper (here) in which Leamer’s important views on how to “Take the con out of econometrics” not having a central role. I was thinking of reworking that paper and, in checking up, learned that he had passed away in February of 2025. So I wanted to get back to this.
Two, I was reading a research proposal from a country’s national science foundation (not the USA and cannot say specifics as a I promised confidentiality). I won’t divulge any specifics of the proposal such that it could be identified but, this proposal was to fund some RCTs in education in one developing country. As motivation for the research the author claimed (and I am parsing, not quoting) that a necessary condition for countries to build the capability to operate a high quality public education system was to do RCTs about both what would work to achieve learning and how to implement those practices that work within the system.
It should only take you a beat or two to realize just how truly surreal this claim is.
First, the author was from a European country with a high quality public system. It is pretty obvious that the system in which this person was educated did not become a high quality system by relying on RCTs about the what and how. Their own lived experience tells them their claim this approach to building capability is generally “necessary” is false.
Second, there are super high quality basic education systems in the developing world. Vietnam, for instance, produces OECD level outcomes on PISA assessments at incredibly low levels of spending (and development generally). There have been many papers and books about “Why is Vietnam so successful at quality education?” (here, here, here, and here) and none of them suggest it was the result of Vietnam’s use of RCTs—because it didn’t happen. As a single counter-example invalidates a claim of “necessity” even a nodding acquaintance with the literature of country’s learning performance produces the realization that RCTs are not a necessary condition.
Third, what is truly surreal about the claim of “necessity” is that there are many, many, counter-examples and not yet a single compelling example. So many Finland, Japan, Korea, Vietnam, Singapore have all been touted at one point or another as very successful education systems and in none of them are the use of RCTs pointed to as an important factor. In contrast, I have not seen anyone point to a single country that has “developed the capacity for high quality learning” predominately relying on RCTs as a tool. So while it is possible that RCTs might play some role in improving education outcomes, claiming “necessity” without a single compelling example and lots of counter-examples is just stunning.
Which led me to the reflection that this author was part of a “community of practice” that strongly believed in the “credibility revolution” for claims about causal impact made in academic papers but, at the same time, was part of a “credulity revolution” for claims about the impact of the “credibility revolution.”
That is, any claim about the practical importance and pressing need for more academic papers in the “credibility revolution” paradigm was taken with complete and total gullibility. To claim that using RCTs was a necessary condition for building high quality education systems needed no proof, needed no evidence, could even be self-evidently false on even a modicum of reflection, but yet could be asserted with the confidence it would be accepted.
This “credulity revolution” has particularly infected the world of development economics and development practice.
The truly incredible, in the literally sense of beggars belief, has not been the rise of a “credibility revolution” in academic circles. What is incredible is the “credulity revolution” in which the very same actors that demand the most stringent criteria of evidence to accept a causal claim in an academic paper make completely unfounded claims about the practical value and impact of the credibility revolution and expect this claims to be accepted with generous credulity.
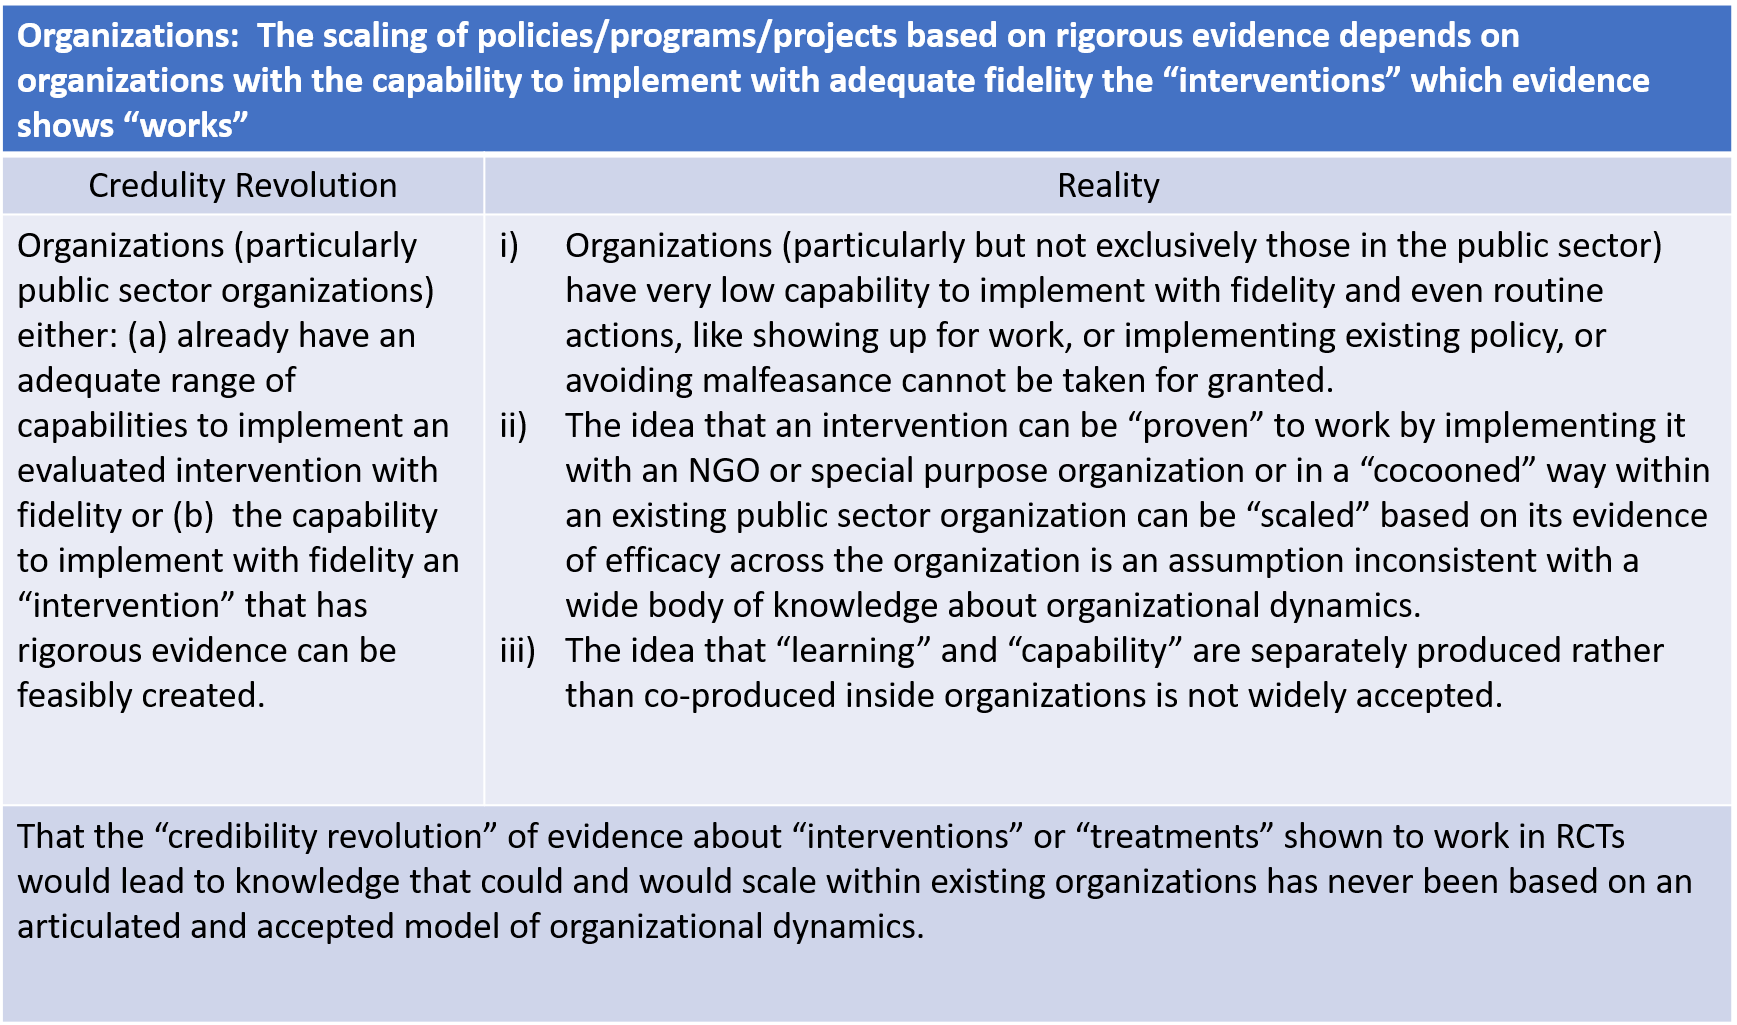
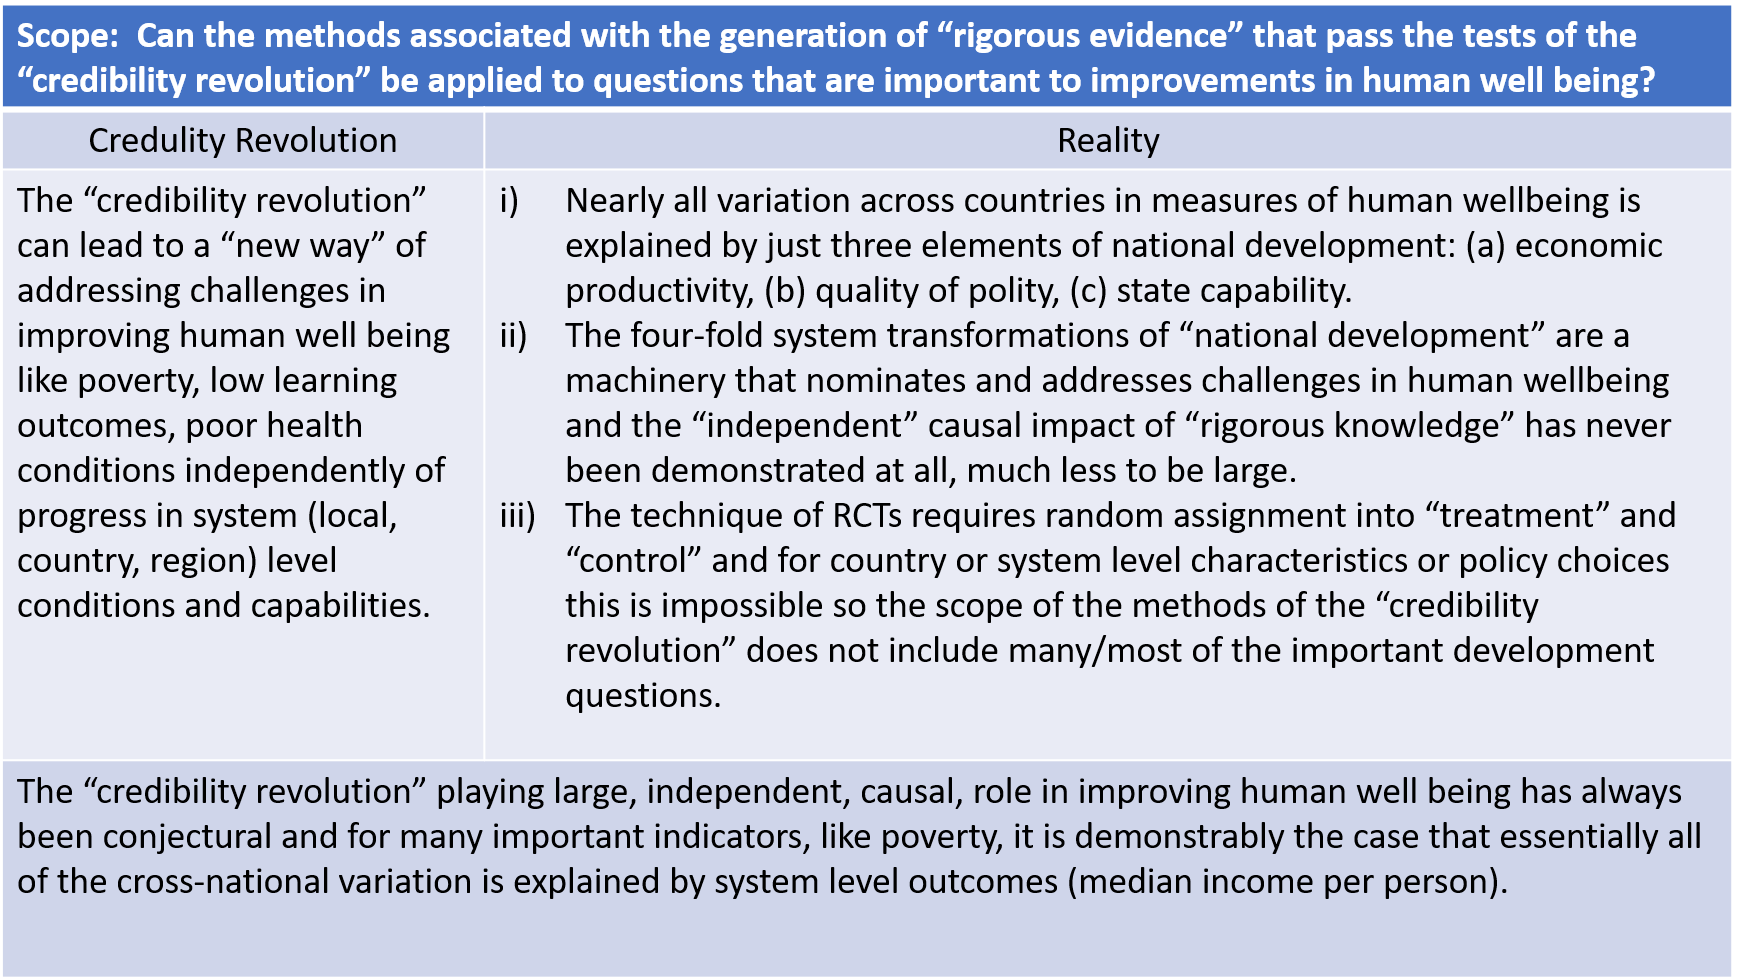
Figure 1 lays out the distinction between the “credibility revolution” about claims in papers and the five domains of a “credulity revolution” in the claims needed to make a causal chain that leads from more credible findings in academic papers to improvements in human wellbeing in the world.
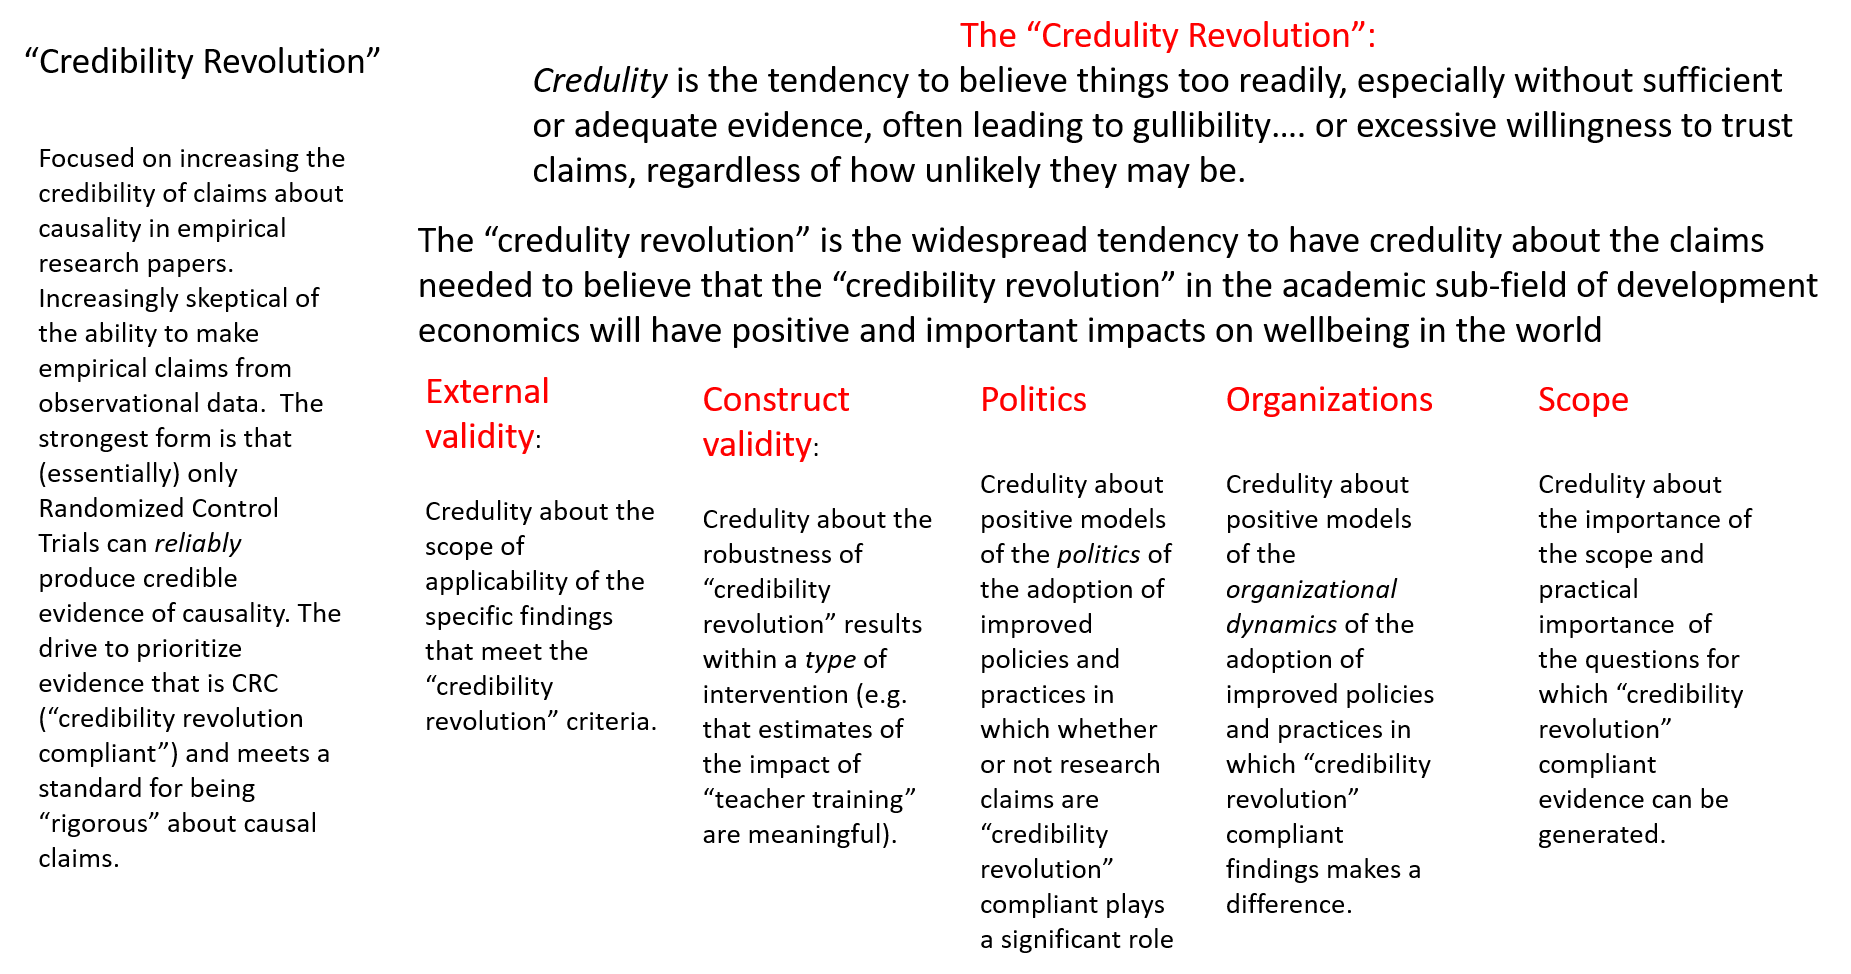
This post just introduces a series of subsequent posts on each of the five elements: External Validity, Construct Validity, Politics, Organizations, and Scope. Those posts will delve into the details of the arguments against the claims accepted with credulity, based on previous research and writings. What follows is not the arguments themselves (so it is premature to give my claims any credence (or reject them), that would also be excess credulity) but just a 10,000 foot overview of the arguments to come.
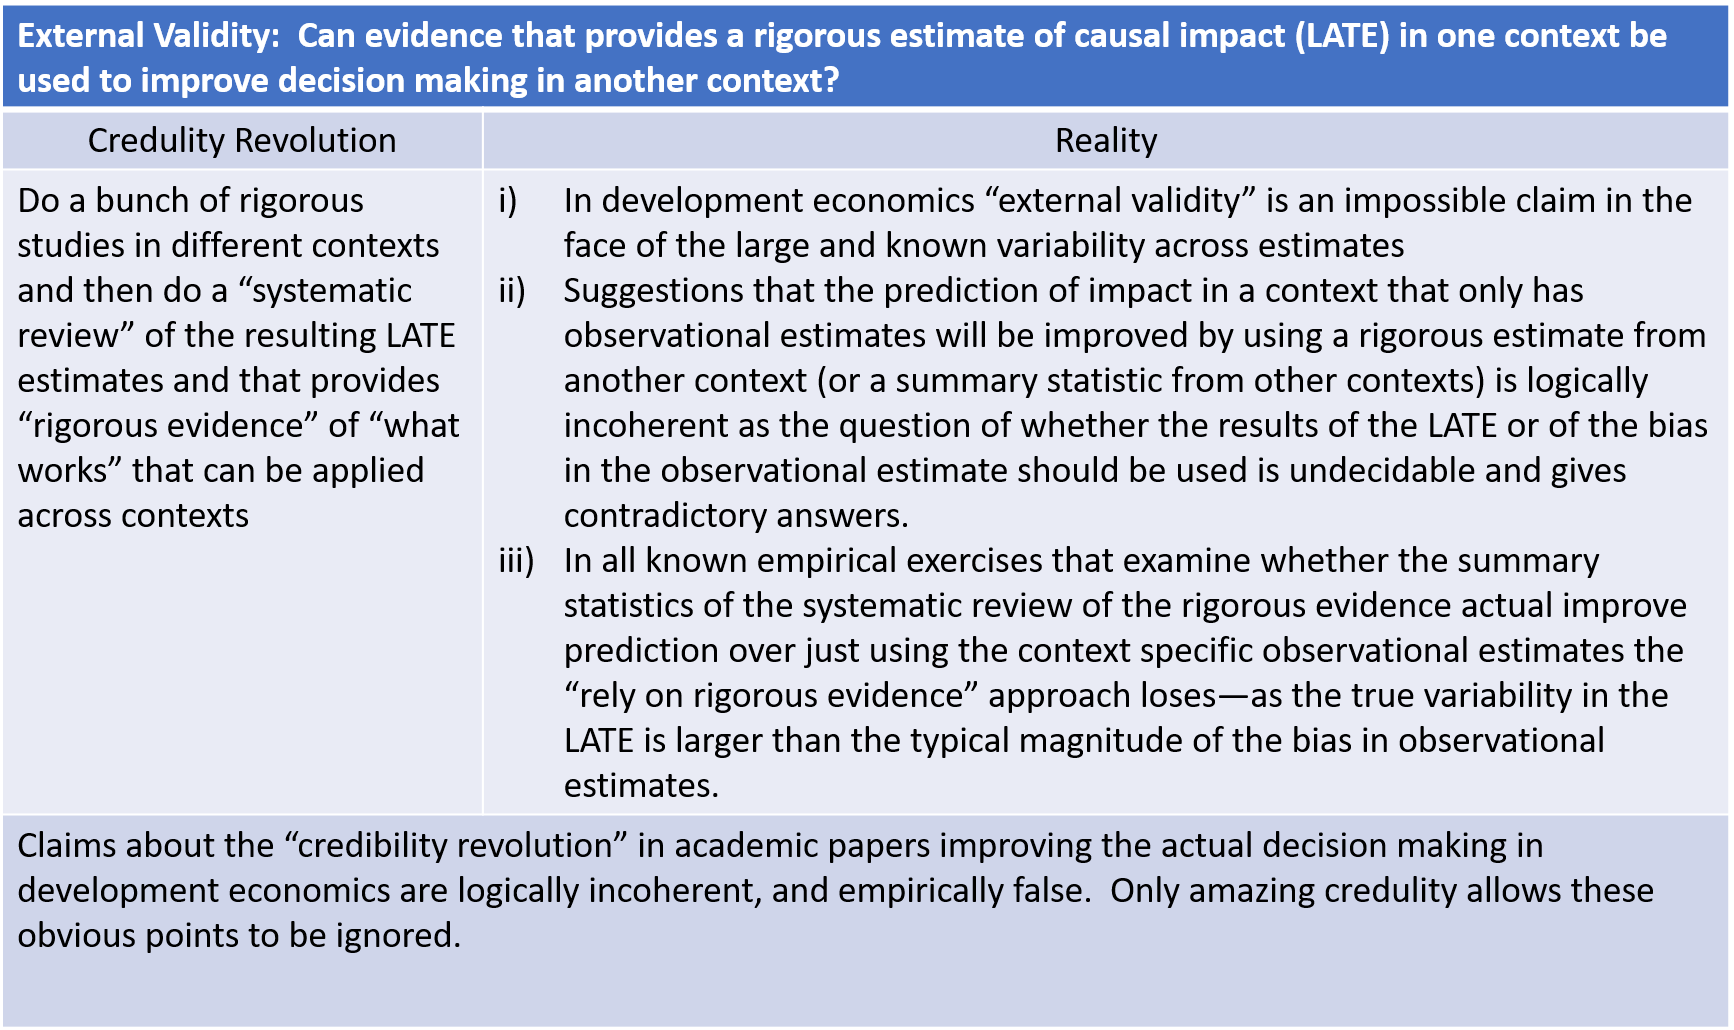
External validity. The research proposal above was for funding RCTs for one small (less than 10 million population) country. The idea was presumably this research applied to more than just this one country, but there is actually no coherent or empirically validated way of saying how research from context A should affect beliefs about causal impacts in Country B.
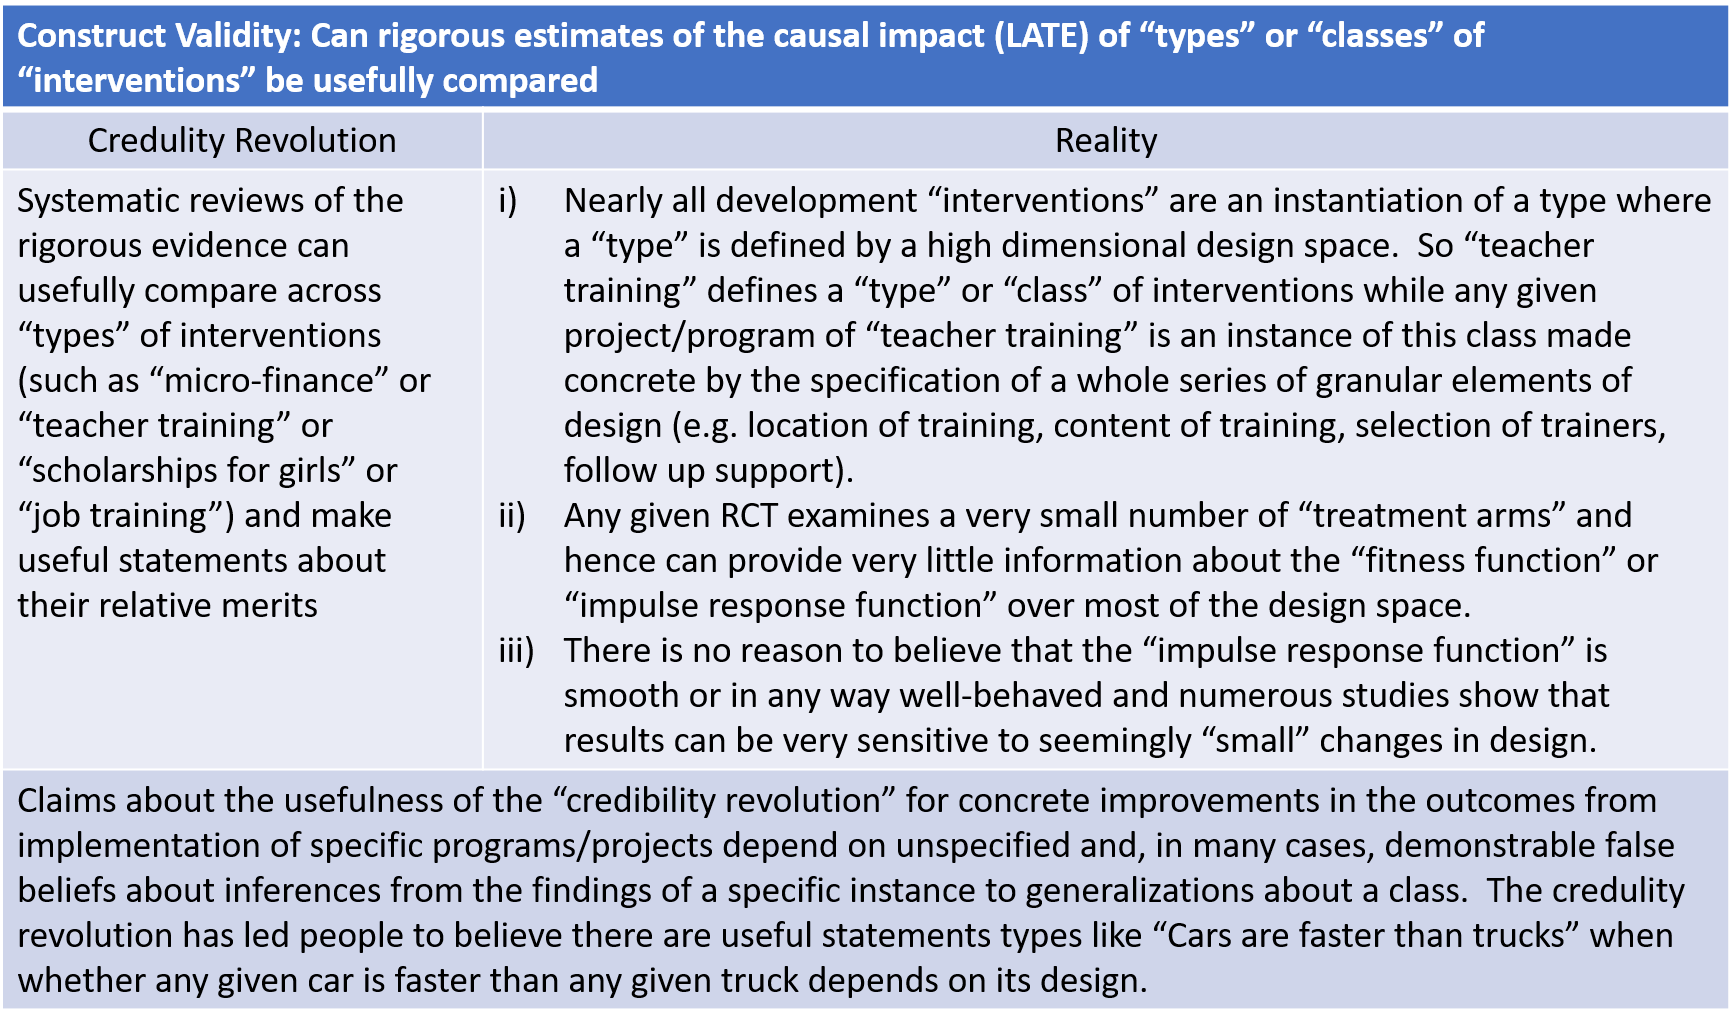
Construct validity. Any given RCT is as assessment of the impact on certain outcomes of a very specific instance of a type of intervention. If one imagines the “response surface” of impact over the “design space” of possible instantiations of a type (e.g. “teacher training” is a type of intervention but characterizing an instance of teacher training requires the specification of dozens of design space elements (e.g. location of the training, duration of the training, intended content of the training, etc.) then most RCTs assess a single point (or perhaps a few points) in the design space. Whether that provides more broadly useful knowledge depends on characteristics of the “response surface” that are not revealed by the RCT itself.
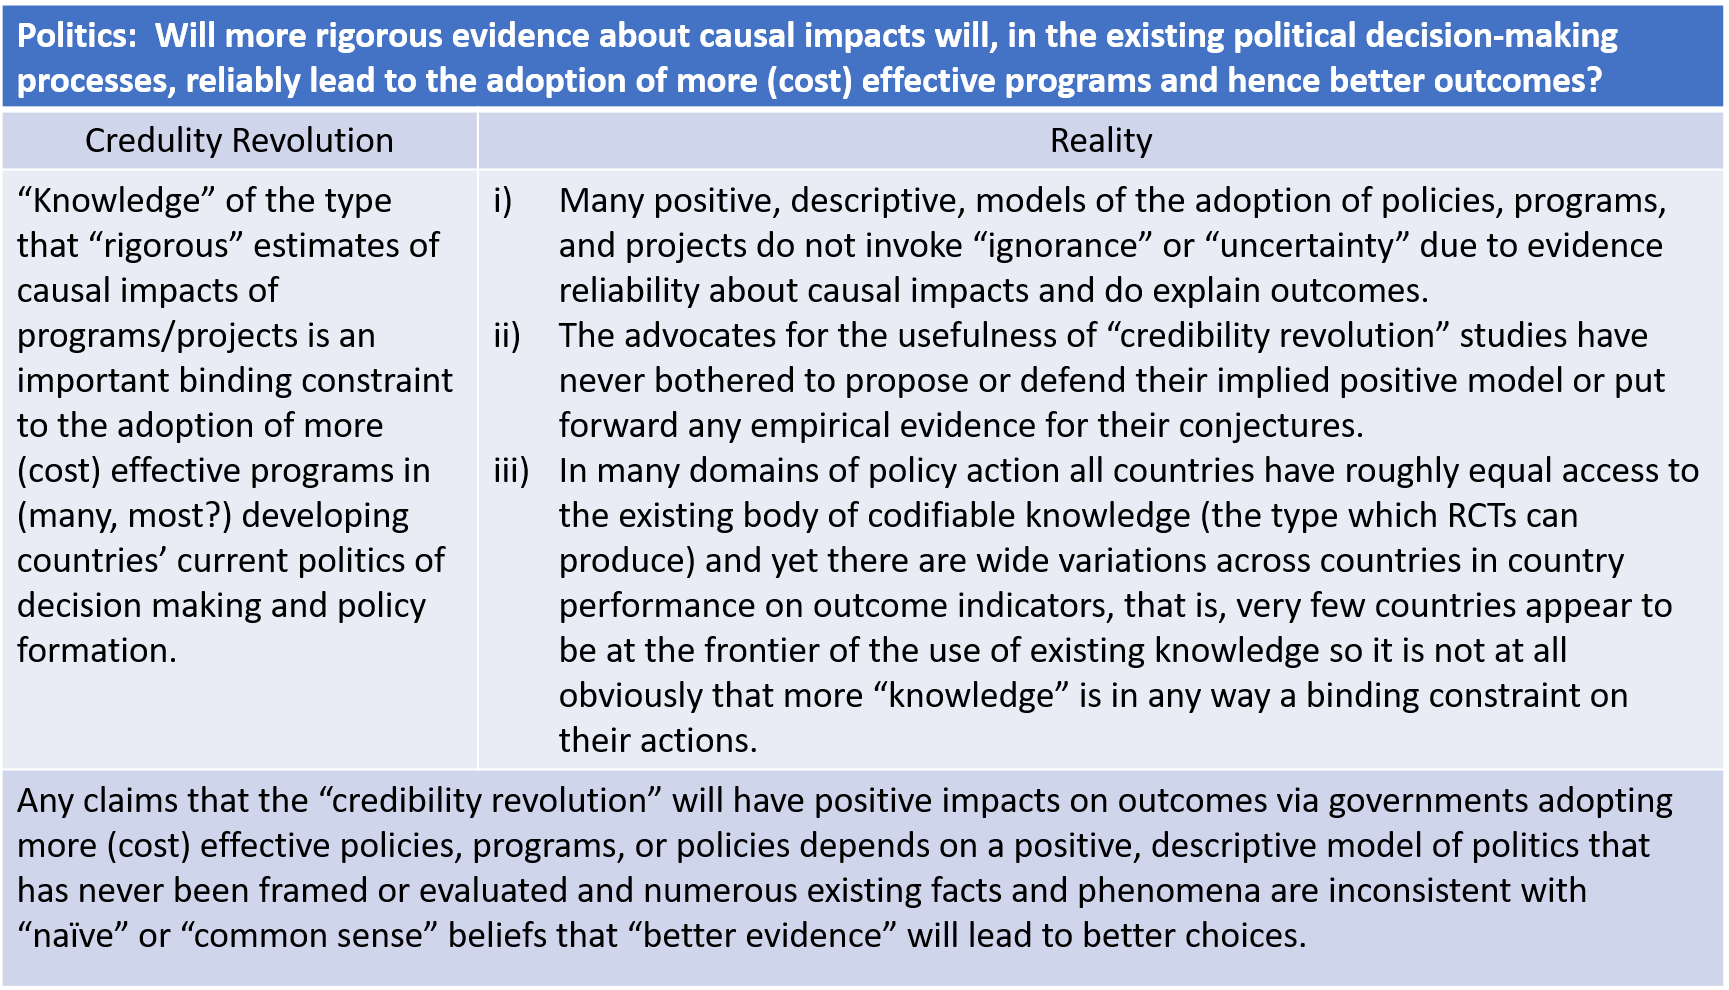
Politics. The idea that a “credibility revolution compliant” (CRC) piece of research will cause “policy makers” (or public officials more broadly) more likely to adopt an intervention which has been demonstrated to “work” (or stop one shown not to “work”) depends on a particular positive model of politics. That model has never been specified nor validated, much less established any credence as a general model of policy/program/project adoption across countries and domains.
Organizations. The move from CRC research to scale requires that an organization have the capability to implement the policy/program/project with sufficient fidelity to achieve the same results. Whether this is generally the case or the case in any instance is a huge open question and cannot be simply assumed away. And the idea that the capability to implement any given “intervention” that has been “proven to work” in another organization (or in a cocooned part of the proposed implementing organization) depends on specific models and beliefs of the building the capability of organizations that may or may not be true.
Scope. The claim is that the “credibility revolution” can build up to be a “different way” to achieve significantly better outcomes on key dimensions of human well being in developing countries. But since many policies and actions produce economic results at the country level (exchange rates, inflation, openness to trade, financial system regulation) and scaled outcomes depend on features of country systems in specific domains (e.g. basic education) then it is practically impossible to generate CRC research on many of the most important questions. How much well being can be improved with CRC research depends on its scope of applicability and it is perfectly possible that is just a very small part of the practical knowledge needed for national development and that national development is what delivers high human well being.
This is not an argument, just the overview. The credulity with which key claims about the potential for real world impact from CRC research has been accepted has been one of the most stunning parts of the “revolution” as it hinges on a huge dose of “skepticism for thee but not for me.”
Lant, interesting piece.
There is a version of this argument that goes deeper than external validity. RCTs or A/B testing in business contexts (and having run a fair number of these outside development settings, the pattern is consistent) are genuinely useful for calibration questions in relatively stable, mature environments where the goal is optimisation. Getting the dosage right. Tuning a known intervention within a functioning system. They perform much less well as systems design tools. The extrapolation problem isn't just geographic; it's categorical. A calibration finding doesn't tell you much about systems architecture.
The questions that actually determine whether countries build functioning education systems, such as how to form a professional teaching corps, how to create a self-sustaining curriculum architecture, and what relationship between central and local pedagogy produces coherent outcomes, are systems design questions. No accumulation of calibration findings can answer them. That's asking the tool to do something it wasn't built for.
Your point about Vietnam illustrates this. Vietnam's PISA performance reflects a systems-design achievement (teaching-profession formation, curriculum coherence, and community expectations), built over decades through processes that RCT methodology couldn't have designed or validated.
Ken Opalo has been making a related point that academic research and policy research are two different enterprises. But the calibration/systems design distinction suggests the problem runs even further into the tool than the institutional structure around it.
Much of the development challenge is systems design rather than calibration. The science foundation proposal you mentioned was implicitly treating a calibration tool as a substitute for systems design capacity. That may be the deepest credulity of all, because it's unseen.
I came across this recently, but this it's fascinating to see more of an exploration of the mindset underlying the aggressive push for adoption of RCTs. One aspect I've found particularly interesting is the way that RCTs were adopted from other sectors in isolation of other evaluation components that are supposed to supplement them. To my understanding, businesses don't run RCTs and then trust that successfully applying the same practices in other contexts will get results. There's an absence of the kind of BI and adaptive management practices that are supposed to accompany implementation.
Ironically, those are probably more useful both for applying ideas at scale, and for iterative development of solutions like you propose in PDIA. There might be more to learn in thinking about how we can build the tech infrastructure that offers BI for implementation fidelity (not AI, quality data architecture for programs), or ways to produce leading indicators on site by site policy effectiveness.